
A managing director types into ChatGPT: “I am looking for suppliers of test bench technology for drivetrains. Which companies belong on my shortlist?” He gets five names. He calls two of them. The third supplier, who would have been the best technical fit, is not on the list – and never learns that the enquiry existed.
The question this article answers is: where does the system get those five names? The answer is more uncomfortable than it sounds. For the most part they come neither from the manufacturers’ own sites nor from the big review platforms, but from third-party comparison articles and rankings – often from sites nobody in the company has on their radar.
Fig. 1 · Key figure
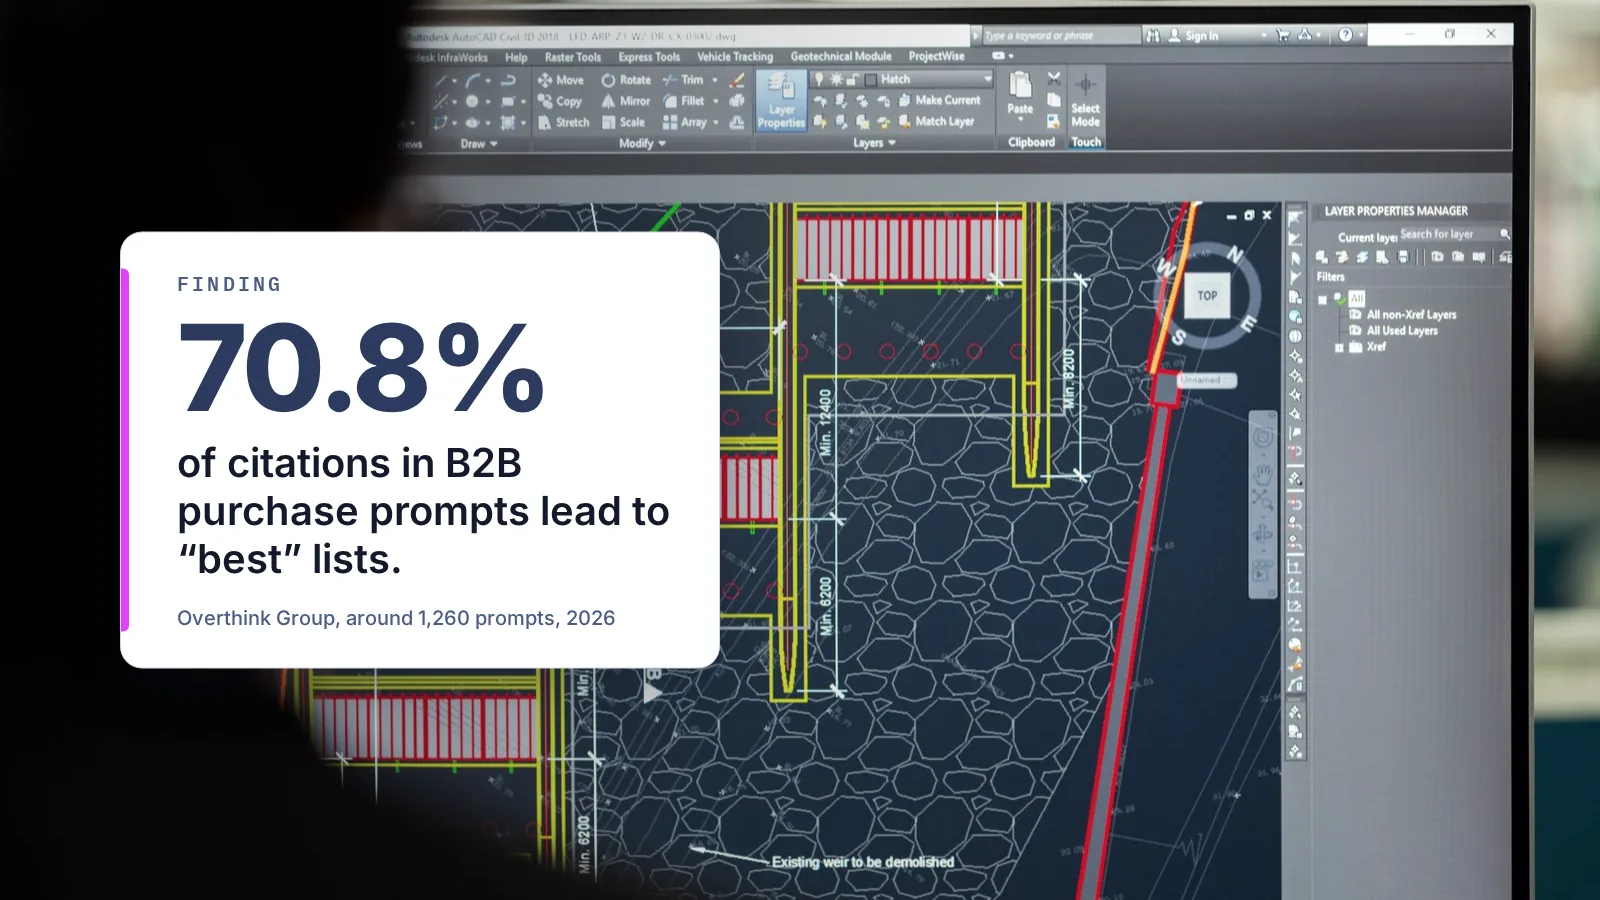
For buying prompts, AI cites lists – not review platforms, not forums
In our model, this building block belongs to the second visibility tier – Tier 2 · Recommended. The first tier makes sure an AI system can read your content at all. The second makes sure it names you because others name you. Comparison articles and vendor lists are the building block there with the most direct link to the buying decision.
What the study actually measured
The Overthink Group, an American content agency, ran around 1,260 buying prompts across four surfaces in June 2026 together with the measurement provider Amadora: ChatGPT, Gemini, Perplexity and Google AI Overviews. The results were published on 14 July 2026.
The set-up matters for putting the results in context, so here is the short version: 250 niche B2B software categories, selected by a search volume of between 150 and 700 queries per month. Four prompt variants per category, including the realistic everyday phrasing “I am researching [category] for my team. Which vendors belong on my shortlist?” One week of runtime.
The core finding: 70.8% of all citations pointed to pages whose title tag contained a superlative – “best”, “top”, “leading” or “popular”. More than half of the cited pages also carried the year in the title, 46.3% both.
Precision is needed here, because the figure is often quoted in shortened form: what was measured was the title tag of the cited page, not its content and not its quality. So the statement is not “AI recommends the best vendors”, but “AI mostly cites pages that call themselves a best-of list”. That is a difference, and it is the actual finding.
The figure that surprises most people
The obvious assumption would be: these lists come from Gartner, G2, Capterra – the platforms that have been rating B2B software for years. The author of the study writes that this is exactly what he expected.
What he measured was something else. All well-known review platforms together accounted for 8.6% of citations. The G2 network – G2 itself, Capterra, GetApp and Software Advice – came to 8.0%, and more than 71% of that came from a single surface: Perplexity.
The remaining 62 or so percentage points of list citations are spread across trade media, industry blogs, consultancy sites – and one category that should not be overlooked.
The part of the finding nobody likes
The study assigned a share of 8.6% to synthetic pages: sites that programmatically generate thousands of rankings, with invented author profiles and no discernible methodology. In ChatGPT they accounted for 14.5% of citations, in Perplexity 11.3%. The Google surfaces showed practically none of the problem – AI Overviews 0.16%, Gemini 0.46%.
We note this for two reasons. First, because it is honest: a considerable part of what these systems currently draw on as evidence does not stand up to scrutiny. Second, because it leads to no recommendation we would make. Appearing on such sites is neither something you can plan nor something you should want, and the situation will not last. Anyone who builds their visibility on it is building on a gap that will be closed.
Why lists and not manufacturer sites
The mechanism behind this is no secret; it follows from the task. A language model asked to compile a shortlist needs a source that names several vendors side by side and ranks them against one another. A manufacturer site structurally cannot do that – it knows exactly one company and says only good things about it.
A comparison page, on the other hand, delivers exactly the format the question calls for: several names, a shared evaluation framework, an order. It is the best-fitting candidate before anyone has even checked its quality.
It gets interesting when you compare the surfaces. For each platform, the study went through the 100 most-cited domains to see whether a vendor of the software in question was behind them. The result was clear: for the Google tools – AI Overviews and Gemini – around three quarters of these top domains were indeed vendor sites. For ChatGPT and Perplexity it was the other way round: around three quarters were not vendor sites.
This has a practical consequence, which the study’s author puts like this: you should not treat “AI” as a single channel. If your target audience mainly uses Google, work on your own pages pays off more. If they research with ChatGPT or Perplexity, what others write about you is what decides.
What a company does with this in practice
Four steps follow from the finding. None of them is a trick, and none works within a week.
1. Find out which lists are cited in your category
This is not an estimate; it is a measurement. Ask the questions your buyers would ask in ChatGPT and in Google AI Overviews, and note which sources are named. Not two questions, but eight to ten – the variation between individual phrasings is considerable.
The wording matters: not “What is the best test bench technology?”, but the phrasing a buyer really uses, with industry, use case and constraints. These are exactly the kinds of questions that now appear as complete paragraphs in search consoles.
The result is a list of ten to thirty sources. This list is your working basis – not a general idea of which platforms are “important”.
2. Close the gap between this list and your presence
Now the comparison becomes concrete: on which of these sites do you appear? Where is a competitor listed and you are not? Where does your entry exist but is wrong – an outdated product name, the wrong category, a superseded positioning?
The most common finding in our work is not absence but vagueness. A company is listed, but under a category nobody searches in, or with a description that does not make clear what it actually offers. For a language model, a vague entry is almost as good as none.
3. Give editorial teams what they need
A place in an editorial comparison is not an ad slot and cannot be bought – at least not where it is worth anything. What makes it more likely is mundane and still rarely done: verifiable information in a form an editorial team can work with. Performance data instead of adjectives. A clear category assignment. Named experts who can be contacted instead of a general inbox.
Our delivery decision here is deliberately narrow: we write comparison articles, but we separate them visibly. A comparison in which the client wins is not a comparison – it is an advertisement, and it is read as one. What gets damaged is precisely the trust this building block is about.
4. Take your own comparison page seriously
The part you control completely is your own page. It appears frequently in the citations of the Google surfaces, and it is the only place where you decide on wording, structure and freshness yourself.
A robust comparison page of your own names the criteria before it names names. It identifies use cases in which another vendor is a better fit. And it carries a date that is accurate – the year in the title of more than half of the cited pages is no coincidence, but a freshness signal these systems respond to.
What a citable comparison page looks like
If 70.8% of citations go to lists and you want to publish a list of your own, the question is what separates a usable one from an irrelevant one. Five properties can be derived from the structure of the measurement and from the way these systems work.
The criteria come before the names. A list that starts with first place claims a ranking without disclosing its yardstick. A list that first states what it evaluates by – throughput, tolerances, interfaces, delivery time – gives a language model the context in which the names stand. It is exactly from such contexts that a model forms its statements about vendors.
Every entry answers the same questions. Inconsistent entries are forgivable for a reader and a problem for machine evaluation. If vendor A’s entry lists its in-house production depth and vendor B’s its founding story, nothing can be compared. A fixed structure per entry – what it is suited for, what it is not, which limitation applies – is the biggest lever and the least used.
There is a case in which someone else wins. This is not politeness but the difference between a comparison and an advertisement. A list without a counter-example is recognisable as self-promotion – to the reader within seconds, and increasingly to the systems that weigh evidence too.
The date is accurate and visible. More than half of the cited pages carry the year in the title. That is not a headline trick: these systems prefer demonstrably current content, and a list with no recognisable revision date is, if in doubt, one from 2019. A year in the title with no update behind it, however, is the opposite of a solution.
The page stands on its own. A section that only makes sense together with the rest of the page loses its meaning as soon as it is lifted out on its own – and that is exactly what happens. These systems work not with pages but with passages. Whatever the paragraph claims has to be in the paragraph.
Why we still do not recommend your own lists as a first step
Your own comparison page is the part you control – and for exactly that reason the weaker evidence. A language model checking which vendors are candidates in a category finds a self-description on your page. If it also finds the same statement in two trade publications, it has confirmation.
The order is therefore: first know which external lists are cited and whether you appear in them. Then your own page. Anyone who starts the other way round has a well-made page and still does not know why they are missing from the answers.
Fig. 2 · Checklist
Five properties of a citable comparison page
- The criteria come before the namesRequiredFirst the yardstick, then the ranking.
- Every entry answers the same questionsRequiredConsistent information can be compared by machines.
- There is a case in which someone else winsRequiredThe difference between a comparison and an advertisement.
- The date is accurate and visibleRequired51.6% of cited pages carry the year in the title.
- Every section stands on its ownRequiredAI cites passages, not pages.
What this finding does not mean
Three caveats belong here, and we would rather state them ourselves.
The study is not about mid-sized B2B companies in Germany. It covers niche B2B software categories in the US market. The author states explicitly that all figures relate to his experiment. Of 1,000 keywords checked, only 264 triggered an AI Overview at all. The direction is robust; the exact shares are not, for your category.
The source has an interest. The Overthink Group sells content strategy and, among other things, writes listicles. That does not invalidate the measurement – the methodology is disclosed and traceable – but it needs saying.
The situation is a snapshot. That ChatGPT currently cites synthetic pages in 14.5% of cases is a flaw in the system, not a law of nature. The study’s author himself expects this to change. A strategy that relies on a system’s current weakness is not a strategy.
What remains is the structural part: buying decisions are increasingly prepared through sources that do not belong to you. That was already the case before AI search, and it has become more measurable.
How this connects with the other building blocks
Comparison articles do not stand alone. They are the second of five building blocks in Tier 2 · Recommended, and they only take effect once the first tier is in place: if an AI system cannot technically read your pages, being on someone else’s list helps little – the confirmation the system looks for when it checks your name is missing. The overall picture – from model knowledge through web search to the selection of names – is described in the article Getting Recommended by ChatGPT as a Supplier.
Closely related is the building block before it, brand mentions on third-party sites. Both describe the same basic principle from two directions: your visibility in AI answers arises mostly outside your own website. The difference lies in the occasion – a brand mention can appear in any context, whereas a comparison article sits exactly where someone is about to make a decision.
If you want to look up the terms behind this: the GEO glossary explains, among others, grounding and query fan-out – the two mechanisms that explain why a single buyer question is broken down internally into several sub-questions and searched for evidence in several places.
The honest conclusion
Nobody can promise you a place on a list, and we do not promise one. What can be planned is the groundwork: knowing which lists are actually cited in your category, correcting the entries that are wrong, and giving editorial teams what they need.
What can be measured is the starting point. If you want to know which sources ChatGPT and Google AI Overviews draw on for your buyers’ questions – and whether your company appears in them – that is exactly what the Digital Visibility Audit measures.
More terms in the glossary: listicles. Besides lists, YouTube is a source companies can fill themselves; how to measure the effect is shown in the analysis of 7,184 AI answers.